At minimum, every waitlist should record contact identifiers, a position, a status, and timestamps, then capture only the extra fields needed to convert that wait into a reservation. These core waitlist data fields drive automation, reporting, and privacy compliance at once: skip one, and you lose the ability to notify people accurately, measure wait times, or defend your data practices later.
TL;DR:
- Recording unique, normalized contact identifiers like email and optionally phone is essential for accurate deduplication and communication.
- Storing the waitlist position as a cached or computed value helps maintain order without drift, but requires careful recalculation on status changes.
- Additional fields like referral codes, source, consent, and metadata enable growth tracking, legal compliance, and flexible querying without schema bloat.
- Implementing reliable storage patterns involves atomic operations such as Redis sets or Postgres conflict clauses to prevent duplicate entries.
- Limiting stored data to only necessary fields and automating retention policies ensures privacy compliance and manages long-term data risk.
Table of Contents
- Canonical waitlist data fields and what each stores
- Industry-specific field examples for education, events, and services
- Storage and data model patterns for reliable waitlist behavior
- Privacy, retention, and data minimization requirements
- Position, status transitions, and lifecycle fields
- Reporting, analytics and operational metrics fields
- How entries are added, prioritized, and what triggers field changes
- Operational best practices and field design
- Our view on field design in practice
- How Ezseat handles these fields for you
- FAQ
- Sources
Canonical waitlist data fields and what each stores
A working waitlist schema starts with a small set of fields that every entry needs, regardless of industry. Get these right and everything else (industry extras, analytics, automation triggers) slots in cleanly.
Contact identifiers come first. Store email as a unique, normalized field (lowercase, trimmed) since it is usually the primary key for deduplication. Add phone as optional, since SMS notification is common but not universal, and full_name for display and verification. Normalize email and phone before insert so the same person cannot join twice under slightly different formatting.
Position is an integer representing rank in the queue. Some systems store it directly on the row and recalculate on every change; others compute it on read by counting rows ahead of a given entry in waiting status. Storing it directly is faster for display but requires careful rewrites when someone cancels or jumps the queue. Computing it on read avoids drift but costs more at scale. Most moderate-volume systems do best storing position as a cached value that gets recalculated by a background job or trigger rather than on every single page load.
Status tracks the entry's state: waiting, invited, joined, declined, cancelled. Pair status with the timestamps that mark each transition (signup_time, invited_at, responded_at) so you can reconstruct the full lifecycle of any entry without guessing.
Referral fields support growth and prioritization. Typical columns include referral_code (a unique string tied to the referring entry), referred_by (the code someone used to join), referral_count (how many people a given code has brought in), and priority_score (a derived number used to jump qualifying entries ahead in the queue). SDK patterns for waitlist entries commonly bundle these directly into the entry object, alongside position and status fields, which confirms this is a standard shape rather than a one-off design choice.
Source and consent fields matter for both marketing attribution and legal defensibility. Capture source (where the signup originated: a QR code, a web form, a referral link), utm_ parameters where relevant, and consent_given with a consent_timestamp if you send marketing messages beyond transactional notifications.
Custom request fields vary by context: dietary notes, accessibility needs, program preferences. Rather than adding a new column every time a new request type appears, store these in a metadata JSON column. This keeps your schema stable while still letting you query specific keys when needed.
A practical field catalog looks like this:
- email: unique, normalized, required for every entry.
- position: integer, cached or computed, recalculated on status change.
- status: enum (waiting, invited, joined, declined, cancelled).
- signup_time: timestamp, set once at creation, never updated.
- referral_code: unique string, generated per entry for sharing.
- metadata: JSON object, holds custom or low-frequency fields.
Keeping metadata searchable usually means indexing specific JSON keys you query often (like a party_size or program_id nested inside it) rather than indexing the whole blob, which keeps lookups fast without bloating your core table.
Industry-specific field examples for education, events, and services
The canonical fields above stay constant, but each context adds a handful of fields that make the waitlist actually useful for that setting.
Education admissions waitlists typically add term (which academic period the entry applies to), program_id, application_id (linking back to the original application record), priority_reason (sibling enrollment, staff child, legacy status), and sometimes grade or year level. The grade field matters more than it looks: it lets an automated matcher offer a spot only when a seat opens in the right grade, rather than flagging every opening to every waitlisted family.
Event waitlists need ticket_class (general admission, VIP, early bird), seat_category or section, group_reservation_id for parties joining together, and a capacity_snapshot recorded at signup time so you can show accurate "spots remaining" figures even as the event fills.
Restaurants and clinics share a similar shape: party_size for a table, seating_area preference (patio, bar, booth) for restaurants, appointment_type (checkup, follow-up, procedure) for clinics, and accessibility_needs for either. These fields are the difference between a waitlist that just holds names and one that lets staff seat or schedule people correctly the moment a slot opens.
- Education: term, program_id, application_id, priority_reason, grade.
- Events: ticket_class, seat_category, group_reservation_id, capacity_snapshot.
- Restaurants/clinics: party_size, seating_area, appointment_type, accessibility_needs.
Not every field is required for every entry. Treat accessibility_needs and seating_area as optional and store them in metadata if they apply to a minority of signups; treat party_size and appointment_type as required since nearly every automated matching rule depends on them.
Storage and data model patterns for reliable waitlist behavior
Underneath the field list sits a storage pattern that has to handle concurrent signups without creating duplicates or losing position integrity. Two approaches show up repeatedly in practice: Redis for speed, Postgres for durability and relational queries, often used together.
For deduplication, atomic operations matter more than application-level checks. A Redis SADD on a set keyed by event or queue ID will silently reject a duplicate email without a race condition; in Postgres, INSERT ... ON CONFLICT DO NOTHING on a unique email index does the same job. Example schemas showing both patterns, including a Postgres waitlist table with signup_time, referral_code, and a metadata JSON column, appear in open-source waitlist API references, which is a reasonable starting point if you are building rather than buying.
Indexing choices determine how fast your position and leaderboard queries run. At minimum, index signup_time (for FIFO ordering), status (to filter active entries quickly), and priority_score or referral_count if you support queue-jumping. Reverse lookups for referral tracking need an index on referral_code so you can resolve "who referred this person" and "how many people has this code converted" without a full table scan.
| Field | Suggested type | Index | Purpose |
|---|---|---|---|
| text, unique | yes | dedup, primary contact | |
| position | integer | yes | ordering, display |
| status | enum/text | yes | filtering active entries |
| signup_time | timestamp | yes | FIFO ordering, wait time calc |
| referral_code | text, unique | yes | reverse referral lookup |
| ip_hash | text | no | fraud mitigation, not raw PII |
| metadata | JSON | partial (by key) | custom fields, low frequency |
Store ip_hash rather than a raw IP address. Hashing the IP with SHA-256 before storage still lets you detect repeated signups from the same source for fraud mitigation, without keeping identifiable address data on file longer than necessary. This pattern, along with sliding-window rate limiting, shows up consistently in open-source waitlist implementations built to resist abuse during high-traffic signup windows.
For the API layer, keep the response to the front end lean: position, totalWaiters, and referralLink are usually enough for a status page. Returning more than that (internal scoring fields, raw timestamps) adds no value for the person checking their place in line and increases the surface area for accidental data exposure.
Privacy, retention, and data minimization requirements
Every field you add is a field you are responsible for protecting, justifying, and eventually deleting. The ICO's guidance on data minimization is built around a simple test: personal data must be adequate, relevant, and limited to what you actually need for the stated purpose. Applied to a waitlist, that means dropping any field you cannot explain a use for.
A practical approach:
- Collect only what a specific feature needs:
phoneonly if you send SMS notifications,accessibility_needsonly if you act on it. - Document the purpose of each field in a short retention schedule or DPIA, even an informal one.
- Store sensitive optional fields (health notes, accessibility details) in metadata rather than dedicated columns, so access can be restricted more tightly.
- Hash identifiers like IP addresses instead of storing them raw, as covered in the storage section above.
Storage limitation is the companion principle: personal data should be kept no longer than necessary for its purpose, with retention schedules and automated review or deletion built in rather than left to manual cleanup.
In practice, that means flagging declined or cancelled entries for anonymization after a set period (30 to 90 days is common for service waitlists), reviewing joined entries on a longer cycle since they may need to stay linked to a transaction record, and running an automated job rather than relying on someone remembering to purge old rows.

Position, status transitions, and lifecycle fields
A waitlist entry moves through a small number of states, and the fields that record each transition are what make automated offers and expiries possible without manual tracking.
- waiting: the default state at
signup_time, no further fields required yet. - invited: set
invited_atwhen an offer goes out, andresponse_deadlineto define the response window. - joined or declined: set
responded_atwhen the person acts, and record which outcome occurred. - cancelled: set
cancelled_atand, ideally, acancel_reasonfield for later analysis. - expired: an automated job sets this when
response_deadlinepasses with no response, logging the reason as "no response" rather than leaving the status ambiguous.
For auditability, decide early whether you want a single row that gets updated in place (simpler, but loses history) or an append-only events table that logs every transition separately (more storage, but lets you reconstruct exactly what happened and when). Many teams keep the current status on the main row for fast queries and log every transition into a separate waitlist_events table for audit purposes.
The most common operational query is "who is next to invite": filter by status = waiting, order by position or signup_time, and apply any priority_score weighting. A close second is reconciling current position against historical state, which is where the events table pays off: you can confirm exactly when someone moved from position 12 to position 3, and why.
Reporting, analytics and operational metrics fields
The fields that make a waitlist usable day to day are not the same ones that make it measurable over time. Reporting needs its own small set of derived metrics, all of which depend on the timestamp fields already in your schema.
- total_waiters: a live count of entries in
waitingstatus. - invited, accepted, declined: counts derived from status, usually grouped by day or campaign.
- avg_wait_time: calculated from
signup_timetoinvited_atorjoined_atacross completed entries. - offer_acceptance_rate: accepted divided by invited, a direct signal of whether your offer window or messaging needs adjustment.
None of these require new raw fields beyond what the lifecycle section already defines: invited_at, joined_at, declined_at, and cancelled_at are the building blocks for every metric above. Add a channel tag (SMS, email, in-app) if you want acceptance rate broken down by notification method, since that often reveals which channel actually gets people to respond.
For grouping, tag entries with term, program, or campaign fields depending on context, so reports can be filtered by cohort rather than only by date range. When exporting to a CSV or analytics pipeline, a practical minimal field set is: email, status, signup_time, invited_at, responded_at, position, and source. Our queue analytics guidance covers how average wait time and acceptance rate get calculated in more detail if you are setting up dashboards for the first time.
How entries are added, prioritized, and what triggers field changes
Not every waitlist entry arrives the same way, and each entry path needs to write a slightly different set of fields to keep downstream automation consistent.
- Auto-generated entries (a booking system automatically waitlists someone when capacity is full) should prefill
source,signup_time, and a defaultstatus = waitingwithout manual input, and validate that email or phone is present before the row is created. - Manual admin entries need extra audit fields:
entered_by(which staff member added the entry) andentry_reason(why it was added manually), since these rows bypass normal validation and need a paper trail. - Referral and lottery flows need
referral_code,referred_by, and, for lotteries, adraw_batch_idand tie-breaker field (often a secondary random value) to resolve ties fairly. - Triggers that update position or status include cancellations (which shift everyone below up by one), capacity changes (which may open multiple spots at once), and manual promotes (which should always log
entered_byfor the same audit reasons as manual entries).
Operational best practices and field design
Keeping the required field set minimal at signup time correlates directly with completion: every extra field is a chance for someone to abandon the form before joining. Push anything optional into metadata and collect it later if needed.
Enforcing a short response window matters more than most schemas account for. We apply a 48-hour offer rule as a standard operational policy, which depends entirely on having response_deadline as a real field rather than an assumption. Without it, expired offers sit unresolved and block the next person in line.
Pro Tip: Store ip_hash and signup_time together on every entry. That pair alone catches most duplicate or bot signups without adding any new personal data fields.
Our view on field design in practice
Running browser-based intake forms across restaurants, clinics, and events taught us that the fields people skip are rarely the ones that matter. A clean email field and a strict 48-hour response window do more for conversion than a dozen optional fields ever will.
— Ezseat
How Ezseat handles these fields for you
If building and maintaining this schema yourself sounds like more plumbing than your team has time for, we built our platform around exactly this field set already. Our intake templates capture the canonical fields (email, position, status, timestamps) out of the box, enforce the 48-hour offer rule automatically, and let you add custom fields through metadata without touching your database structure.
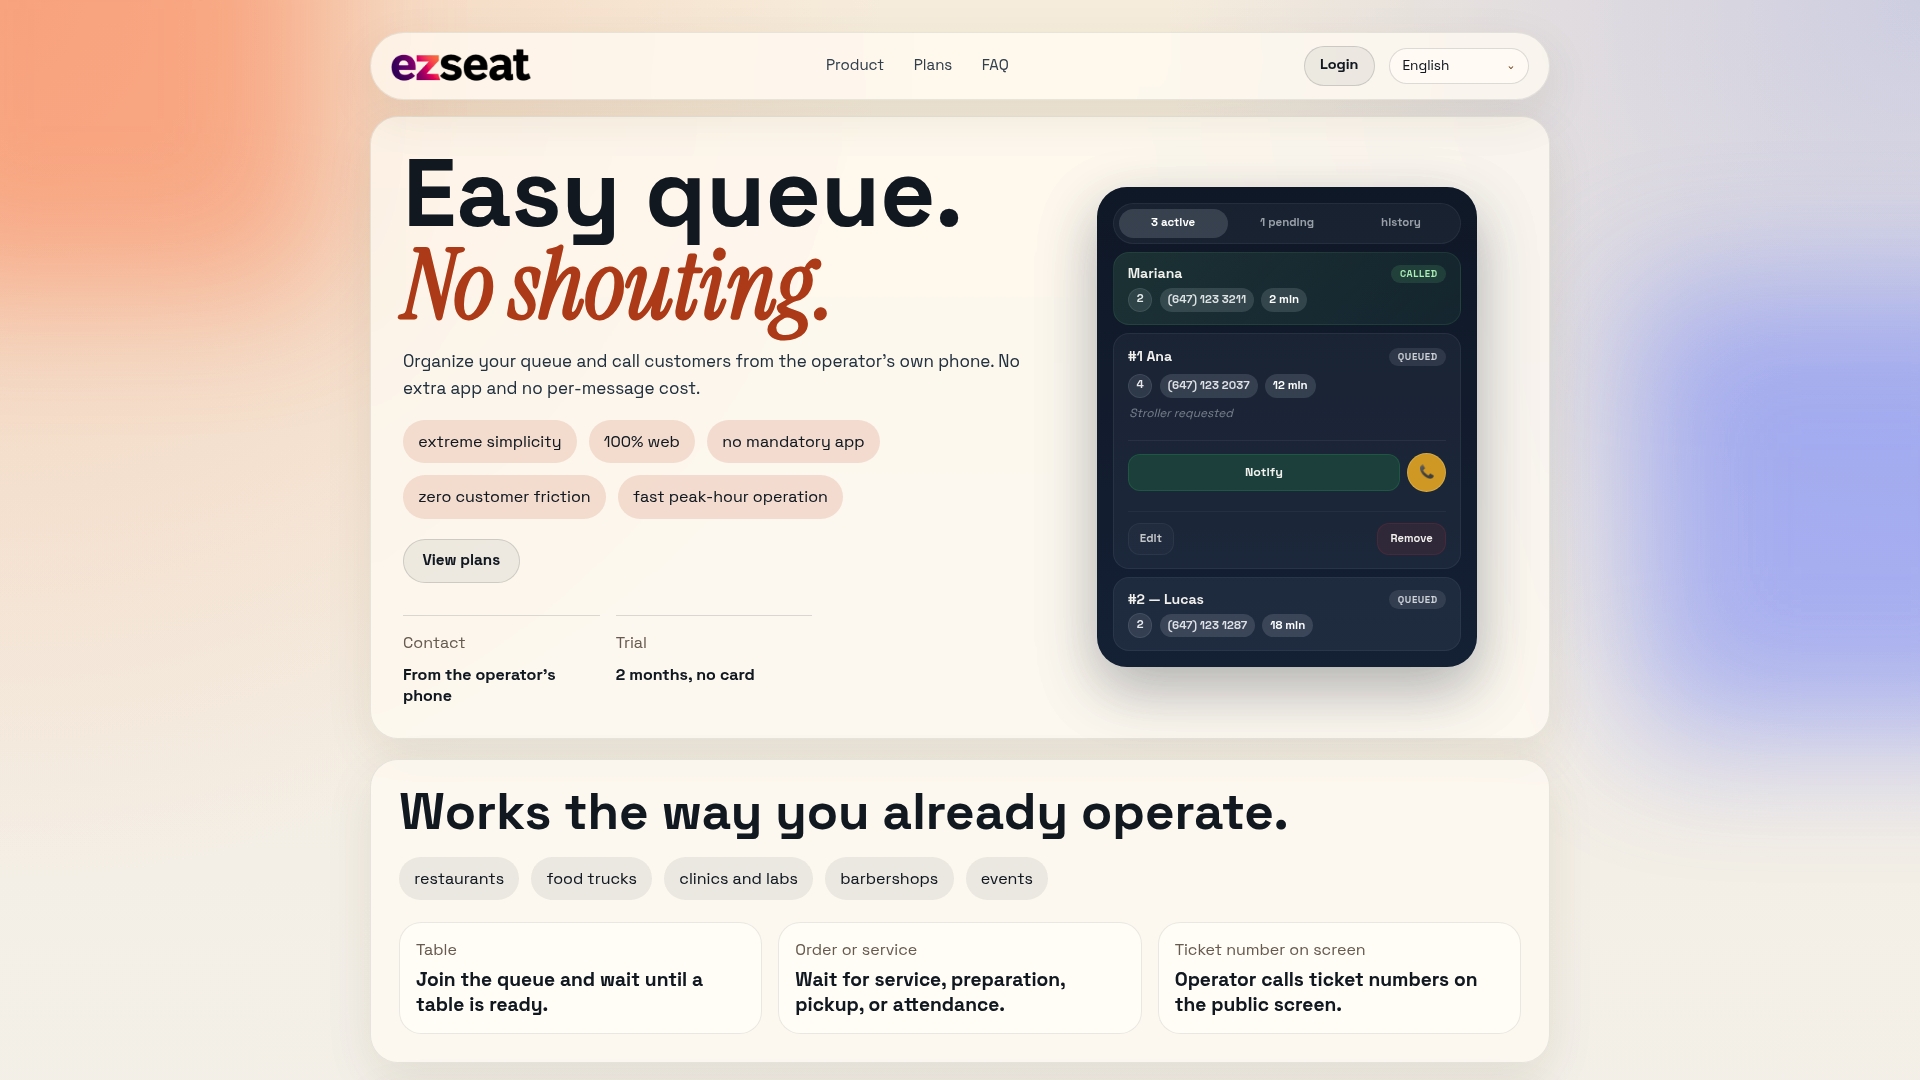
- Browser-based intake forms with no app download for customers or guests.
- Automated offer expiry and position recalculation built into every queue.
- Exports and analytics covering wait time, acceptance rate, and referral tracking.
- Pricing details are available on our website's pricing page.
Whether you are running a single restaurant queue or managing waitlists across multiple event dates, you can see how the field structure works in practice by visiting Ezseat and starting a free trial.
FAQ
What percent of waitlisted applicants get accepted?
Acceptance rates vary widely by program, institution, and term, so there is no single figure that applies across contexts. Tracking your own offer_acceptance_rate field, calculated as accepted divided by invited, gives a far more useful number than any general estimate.
What are the odds of getting in a waitlisted class or program?
The odds depend heavily on how many spots open up, how the waitlist is prioritized, and how many people ahead of you decline their offer. Fields like position, priority_score, and historical offer_acceptance_rate are what administrators use to estimate this for a specific queue rather than relying on a general rule.
Is getting waitlisted the same as a rejection?
No, being waitlisted is a distinct status from being rejected. A waitlist entry with status = waiting means a decision is still pending, and the person remains eligible for an offer if a spot opens, unlike a rejection, which is final.
How likely is it to get into a waitlisted program?
Likelihood depends on program-specific factors like how many people are ahead in position, how many typically decline their offer, and how the program prioritizes fields like priority_reason or referral_count. There is no universal probability, since each waitlist's conversion rate differs by context and by how it is managed.
Sources
- sdks/waitlist.as/index.ts
- Principle (c): Data minimisation | ICO
- Principle (e): Storage limitation | ICO